Ditching llm-scaler: Qwen3.8-27B on my B70
Patching vLLM with agents was a headache, but it was well worth the trouble.
I bought an Intel Arc Pro B70 for $1,300 at Canada Computers so I could run Qwen locally. I bought it before Qwen3.8 came out. When it landed, I wanted to get it running right away.
Intel inference is the less mature path. With an Intel card, new releases can mean waiting for Intel to patch llm-scaler rather than getting the latest vLLM changes from day one. There is a smaller open-source community working on Intel and llm-scaler, and Intel cards are less common than an NVIDIA RTX Pro 6000 or an AMD R9700. That’s the tradeoff.
Qwen3.8 uses the same Qwen3.5 architecture as Qwen3.6, so I got it working in llm-scaler from day one. But MTP didn’t work properly, and both prompt processing and generation were underwhelming. I had just spent $1,300 on the GPU. With 604 GB/s of memory bandwidth, I expected more than 25 tokens a second. Something in the stack wasn’t right.
I don’t have a background in inference engineering. I took some machine-learning and AI courses at university, but I didn’t know how vLLM worked. I turned to my trusty agent, GPT-5.6 Sol, and asked it to help me put an inference stack together.
Leaving llm-scaler
We started by looking at what llm-scaler is: a fork of vLLM. Going straight to vLLM meant access to newer fixes, patches, tool-call parsing, and other things Intel hadn’t pulled into its fork yet. But I still needed Intel’s work to make models run properly on its XPU. The goal was to use upstream vLLM and bring over the Intel changes this setup needed.
I had already hit MTP failures with other stacks. My Qwen3.6 AutoRound experiments produced corrupted speculative output with graph replay, or coherent but slow output without it. A later Qwen3.8 development-stack attempt broke down under longer prompts. Those results told me those particular combinations weren’t working; they didn’t tell me the B70 or MTP itself couldn’t work.
I also searched Reddit for someone who had got this setup working and found SergiioB’s Intel Arc Pro B70 inference cookbook. I followed its checkpoint choice and two required runtime patches. The recipe and patches are SergiioB’s work. My result is the deployment and measurements on my machine, and I’m grateful for the work that made it possible.
The stack that finally worked
| Piece | August 20 setup |
|---|---|
| GPU | One Intel Arc Pro B70; 32,656 MiB reported by PyTorch XPU |
| Host | Ubuntu 26.04 LTS, xe driver, 230 W GPU power cap |
| Model | Qwen3.8-27B GPTQ INT4, symmetric group-128, with BF16 MTP tensors |
| Runtime | Pinned vLLM XPU image; installed vLLM 0.27.2rc1.dev77+gac7509e2b.xpu |
| Runtime patches | patch_mtp_nightly.py, then patch_mtp_boundary.py |
| Execution | FP16 target compute, BF16 draft, FP8 KV cache, XPU graphs |
| Speculation | MTP4: four proposed draft tokens per verification round |
| Production limits | 131,072 total tokens; one sequence; scheduler ceiling 8,192 |
| Production cache | Exact-prefix caching enabled after a separate functional canary |
The main model weights are GPTQ INT4, but the checkpoint’s MTP draft weights are BF16. The first patch keeps those draft weights out of the INT4 quantization path so they stay BF16. The second handles the very end of the context window: the B70’s XPU kernel needs a complete speculative group, so vLLM finishes an incomplete final group without speculation. Those two fixes let me run MTP4 with XPU graphs enabled; I didn’t have to turn graphs off to make it work.
I use this as a pinned compatibility bundle, not a handful of flags to scatter onto any nightly. B70_MTP_BF16_DRAFT=1 keeps the draft precision explicit. The setup and measurement record has the image digest, model revision, patch hashes, upstream recipe, and benchmark controls.
These results validate that exact bundle. They don’t tell me which patch or version change fixed what on its own, and they don’t prove that removing llm-scaler alone makes a particular speed difference.
MTP4 now earns its place
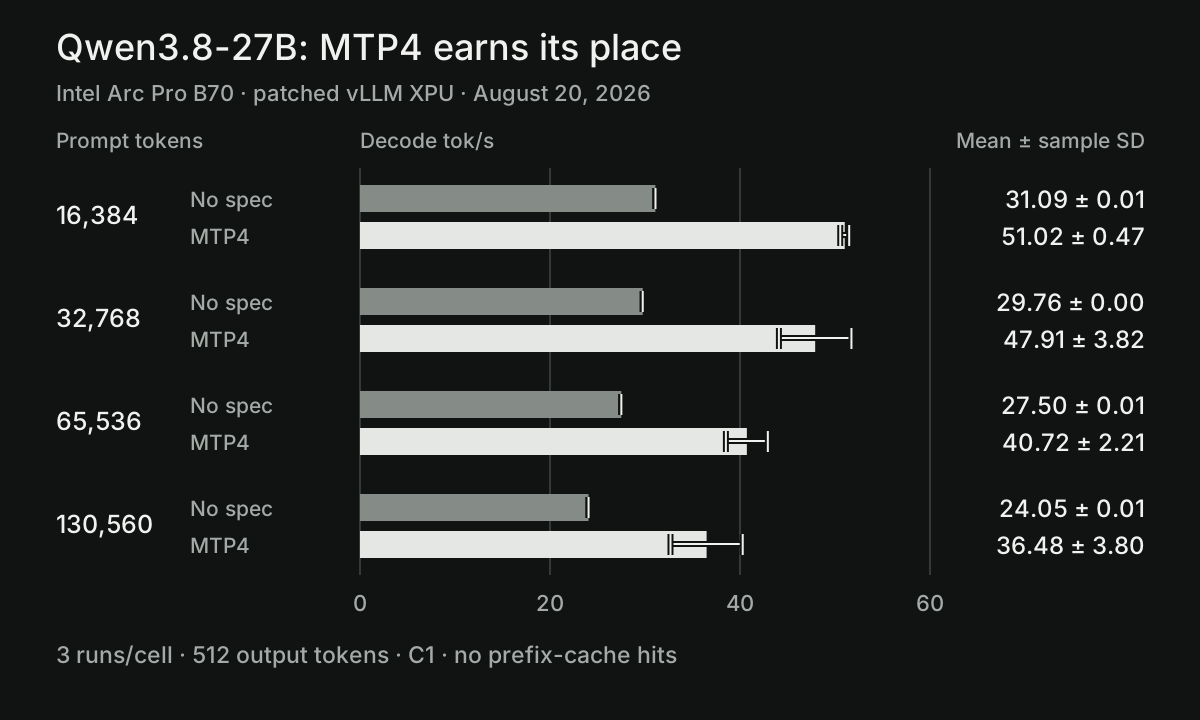
I wanted a long session to feel fast, not just a short prompt. I tested four prompt depths with exactly 512 output tokens each. At every depth I used a generic warmup, a same-shape full-output warmup, and three measured runs with distinct prompts. I sent one request at a time, turned off prefix caching, and confirmed every measured request had zero cache hits.
| Actual prompt tokens | No speculation, tok/s | MTP4, tok/s | Decode speedup |
|---|---|---|---|
| 16,384 | 31.09 ± 0.01 | 51.02 ± 0.47 | 1.64× |
| 32,768 | 29.76 ± 0.00 | 47.91 ± 3.82 | 1.61× |
| 65,536 | 27.50 ± 0.01 | 40.72 ± 2.21 | 1.48× |
| 130,560 | 24.05 ± 0.01 | 36.48 ± 3.80 | 1.52× |
These are means ± sample standard deviations, not confidence intervals. I measured decode after the first generated token: the remaining 511 tokens divided by the time from the client’s monotonic clock. The 0.00 deviation is small but not zero; it’s just rounded.
All 12 MTP4 completions passed the recorded mechanical checks and output-coherence review, as did all 12 no-speculation controls. At the longest prompt, the three MTP4 runs measured 32.11, 38.94, and 38.41 tok/s. There was no recorded EngineCore failure, out-of-memory error, graph failure, speculative-state error, or GPU reset during the campaign.
A note on GPU utilization: I don’t have a measurement here of how busy the GPU was. gpu_memory_utilization is a memory budget for vLLM, not a reading of GPU activity. The no-speculation run used 0.90 and MTP4 used 0.88, so this is a comparison of two pinned configurations, not a one-setting-at-a-time test. Both servers allowed 64 sequences, but I sent just one request at a time. My production profile is stricter still: one sequence and prefix caching on, a configuration I didn’t re-benchmark with this matrix.
MTP4 was coherent at every tested prompt depth and decoded 1.48–1.64× faster than running without speculation. The 131,072-token limit is for the whole context: input plus output. At the largest tested depth, I sent a 130,560-token prompt and left 512 tokens for the answer. It doesn’t mean you can send a 131,072-token prompt and then generate more.
Faster decode is not the same as a faster whole request
MTP speeds up generation after the first token; it doesn’t make the B70 process the prompt faster. For a long prompt, that part can take most of the request.
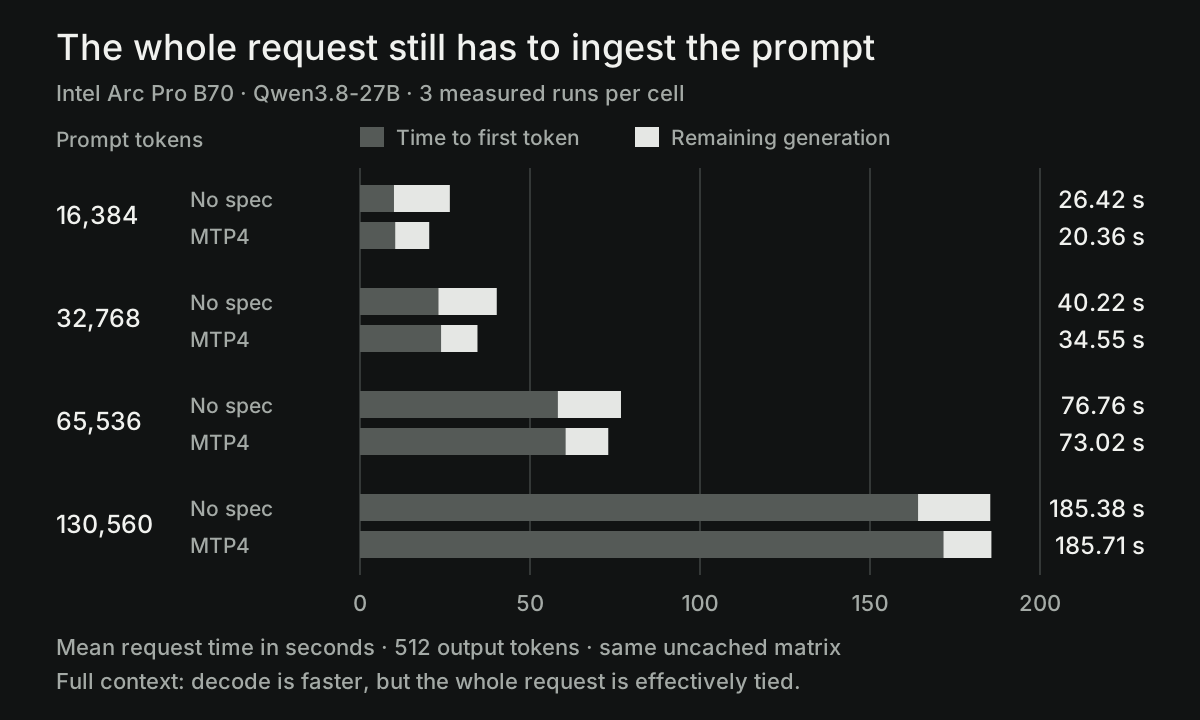
At 16K, the full 512-token request went from 26.42 to 20.36 seconds. At 32K, it went from 40.22 to 34.55 seconds.
At 130,560 prompt tokens, MTP4 took about 171.59 seconds to produce the first token. The whole request took 185.71 seconds, compared with 185.38 seconds without speculation. The decode got faster; the complete request didn’t, because prompt processing ate up the difference.
Turning this into the setup I use
On August 20, I moved the working stack into my request-driven serving setup. It starts the backend when needed, shuts it down after it’s idle, and keeps it behind the manager instead of exposing the backend directly. I also rehearsed its smoke checks, idle/restart behavior, and rollback and redeploy.
At startup, the production profile reported 17.38 GiB for model loading, 5.65 GiB available for KV cache, and 140,530 tokens of KV capacity with prefix caching on. Those are startup allocation figures, not a breakdown of every byte in GPU memory. I set the sequence limit below the reported cache capacity.
I also checked whether prefix caching worked. Repeating an exact 43,264-token chat prompt reused 39,936 tokens and returned the same output token IDs. A 94-token repeat had no cache hits, consistent with the cache’s block size. This was a functional check, not a speed test or a full check of eviction, restart, and tool-call behavior.
One correction to my earlier wording: the August 20 benchmark runs above were text-only, but Qwen3.8 was image-capable all along. My serving manager had a setting that forced the profile to language-only. I changed that setting and configured the profile to accept both text and images; image input now works. The charts here are still text-only results; I haven’t benchmarked image requests as part of this campaign. Tool calling is configured with qwen3_xml. Coherent outputs are a useful check, not a coding benchmark or proof of model-quality equivalence.
Evidence, credits, and the earlier chapter
These throughput numbers are from the retained August 20 campaign, not new runs. The public bundle includes the records and methodology, with its limits spelled out. If you use an agent, give it the bundle README and ask it to look through the evidence and use whatever is helpful.
- All 24 measured-run records, with timings, token counts, acceptance measurements, and output hashes.
- The eight-cell summary and correctness results.
- Setup, methodology, source hashes, and production differences.
- Bundle notes and reproduction limits, and the chart generator.
The cookbook, checkpoint, and runtime patches came from the linked upstream work; GPT-5.6 Sol helped me with the vLLM changes. The records let readers check the arithmetic. Original prompts, completions, and private operational captures aren’t included, so they can’t independently verify the output-coherence review.
The earlier version of this post and its original evidence bundle are still available. That chapter is about Qwen3.6, AutoRound, Gemma, GGUF, and the MTP failures on those setups; its numbers aren’t Qwen3.8 results.